THE CNERD AI WORKBENCH · GUIDE 01
Build an AI setup
that works for you.
Start with a useful job. Choose where your AI runs. Build it one practical step at a time.

Start here
Which model should you run?
Start with the computer you already own and one task you want to improve. This draft picker estimates a model fit and prepares setup commands for review.
 ChatGPT
 Claude
 Gemini
 DeepSeek
 Qwen
 Gemma
 GLM
How good is it?
This draft chart compares published benchmark scores, not overall equivalence. Scores for normal builds are referenced to the Epoch Capabilities Index. The chart does not establish the performance of modified builds.
Working dataset dated 5 November 2026. Model availability, prices, and benchmark values still need CNERD verification before publication. Memory fit is an estimate; confirm it on your own machine.
Part 2 · Explore the cloud option
What an abliterated model is
A modified model changes how an existing model responds. Abliteration is one approach to altering refusal behavior. For our workbench, the useful question is whether a particular build handles your task reliably, with the right privacy and control.
Abliterated or uncensored?
- Abliterated: that one direction is removed from the weights.
- Uncensored: a broad label used for different modifications. Read the model documentation and test its behavior.
Does it get dumb?
Changes to a model can affect answer quality and tool use. Compare the normal and modified builds on the same small set of tasks. Record correctness, speed, and mistakes before choosing one.
Three warnings
- You do not own what you only rent. A host can remove a model. Save the weights if you need them.
- Uncensored does not mean private. An API still reads every word you send.
- The judgement is now yours. Review the output and use the model on your own work and systems.
Where to get one by API
Draft comparison, per 1M tokens. Check the linked provider documentation for current models and rates before spending.
abliterated-model-large-flashDeepSeek V4.1 Flash 1017. 1M context, text and images.abliterated-model-large-v2GLM-5.3. 1M context, text only.abliterated-modelBase model not named. 262K context, text and images.The API route is not local. What the model reads goes to the provider. abliteration.ai says: "Prompts and completions are processed transiently and not stored by default." That is their claim. Nobody here audited it.
Our first project: a small business helper
Use a fictional service request to build a simple job intake screen. Start with a customer name, a job description, and a next action. Then test whether the app saves and shows the information correctly. Record your own time and API cost as you go.
Point Claude Code at it
- Sign in at abliteration.ai/console and make a project key. It starts with
ak_. - Run the lines below, with your key.
- Start
claudein a new folder.
export ANTHROPIC_BASE_URL=https://api.abliteration.ai
export ANTHROPIC_AUTH_TOKEN=ak_YOUR_API_KEY
export ANTHROPIC_DEFAULT_OPUS_MODEL="abliterated-model-large-flash[1m]"
export ANTHROPIC_DEFAULT_SONNET_MODEL="abliterated-model-large-flash[1m]"
export ANTHROPIC_DEFAULT_HAIKU_MODEL="abliterated-model-large-flash[1m]"
claude
Add Reverse Engineer Anything
REA is a free MIT tool set for AI agents. It inspects apps, sites and binaries. Your agent uses it to learn how an app behaves.
npx rea-agents setup
The rule: copy what an app does, never its code. Rebuild the behaviour from scratch, with your own name and design. Many apps ban reading the code inside them, so check the app's terms and your local law first.
Check its work. A finished-looking screen is only a starting point. Check saving, validation, keyboard use, and phone layouts. Keep a short record of what passed and what still needs work.
Do it all with one prompt
Set me up to run an uncensored model through Claude Code. Keep my normal Claude Code as it is.

1. Ask for my abliteration.ai API key. Save it in a file only I can read. Never print it.
2. Read https://docs.abliteration.ai/integrations/claude-code.md. Make a launcher called claude-abliterated from it, with its own CLAUDE_CONFIG_DIR. Use the model abliterated-model-large-flash.
3. Run npx rea-agents setup for that launcher only.
4. Send one short test message. Show me what it cost.

Then help me build a small job-intake tool for a fictional service business:
- Ask what information the business needs. Write down the fields, actions, and expected outcomes.
- Build my own version from scratch, as one HTML file.
- Use original code, wording, and CNERD AI styling: electric blue, deep navy, and white.
- Test every feature in a browser after each pass. Do not say done until you have. List what you could not test.
Stop at $2 of spend. Everything the model reads goes to abliteration.ai, so give it no private files.
Part 3 · Keep the work close
Run it on your own machine
Start with a fictional job note and ask a local model to turn it into a clear task list. Local inference can keep model requests on your computer, but connected tools and cloud services may still send data elsewhere. Check those connections before adding client information.
Start with the best normal model
The picker estimates which models fit your hardware. Verify the model tag and download size with the publisher, then try a small task. A model fitting in memory does not guarantee that it will be fast enough for your workflow.
Optional experiment: compare a modified build with its normal version using the same sample task. CNERD performance measurements will be added after our own test run.
How far behind is local?
Use the chart as a starting point, then test the task you actually care about. A local assistant that handles your daily notes well may be more useful to you than a higher benchmark score.
Step by step
- Install Ollama. Mac and Linux:
curl -fsSL https://ollama.com/install.sh | sh. Windows:irm https://ollama.com/install.ps1 | iex. Or use the download page. - Pull your model. The picker writes this line for you.
- Give it room to think. Agents need 64K of context:
OLLAMA_CONTEXT_LENGTH=64000 ollama serve, or the slider in the Ollama app. - Start Claude Code on it:
ollama launch claude --model <your model>. - Check it fits. Run
ollama ps. If the PROCESSOR column shows CPU, the model is too big and will run slowly.
Save the weights
A host can remove a model. Your copy stays. Models live in ~/.ollama/models on Mac and Linux, and in %HOMEPATH%\.ollama on Windows. Copy that folder to a spare drive.
The model traffic stays on your machine. Claude Code itself may still call home. This pack did not test that. Turn off Wi-Fi and try it if you need to be sure.
Get your own model guide
Write me a model guide for this machine. Ask before each download.

1. Check my chip, memory, GPU memory and free disk.
2. Pick the best normal model that fits, from this draft list. First check ollama.com for current availability and requirements. These are estimates, not CNERD test results:
- 8 GB: qwen3.5:4b (3.32 GB download)
- 16 to 24 GB: qwen3.5:9b (6.55 GB)
- 32 to 48 GB: qwen3.8:27b (17.74 GB)
- 64 GB and up: qwen3.8:27b-q8_0 (29.98 GB)
- Any Mac with an Apple chip and 32 GB or more: use qwen3.8:27b-mlx instead (18 GB, needs Ollama 0.32.12). Verify the memory requirement before downloading.
3. Give me one page: the model, the download size, whether my disk fits it, the exact commands, and whether I should use an API instead.
4. If I say yes: install Ollama if it is missing, pull the model, start Ollama with OLLAMA_CONTEXT_LENGTH=64000, then run ollama launch claude --model <the model>.
5. List any outside connection the launcher makes. Tell me plainly what you could not check.

Optional: each model has an abliterated build from huihui_ai on ollama.com. It needs its own task and performance checks. Only pull one if I ask.
How fast is it on your Mac?
Test how fast my local model runs on this machine. Do not download anything without asking.

1. Run ollama list. Ask me which model to test.
2. Run the same short prompt 3 times with: ollama run <model> --verbose. Read the eval rate each time. The first run may be slower because it loads the model.
3. Run ollama ps. Check that the PROCESSOR column says GPU.
4. Give me one small table: model, my chip, memory used, GPU or CPU, tokens per second for each run, and the average.
5. Add one line: is this fast enough for chat, and for a coding agent?
Report only what you measured. Do not guess.
Part 4 · Add a voice
Give your AI a voice
Give your helper one short message to read aloud, such as a summary of tomorrow’s jobs. Start with a licensed stock voice and sample text. Add speech input and a conversation loop only after the first step works.
Voice tools draft
Use the guided prompt below, or review the downloadable helper scripts. The CNERD package is a working draft; live voice and model integration still need a complete test.
mkdir -p ~/.claude/skills && unzip -n ~/Downloads/cnerd-voice-tools.zip -d ~/.claude/skills/
Or use one prompt
Add a voice to my AI with Fish Audio, one step at a time.

If the fish-voice skill is installed, run /fish-voice. If not, read https://docs.fish.audio first.
1. Tell me to open https://fish.audio/ in my browser and make a Fish Audio account. Then help me get a key at https://fish.audio/app/developers/get-started/ and save it in ~/.config/fish-voice.env. Never print it.
2. Check the key works.
3. Help me pick a voice. Clone a voice only if it is mine, or I have written consent.
4. Turn one sentence into speech. Save the file. Do not play it unless I ask.
5. Turn that file back into text.
6. Build a voice loop with my own model as the brain.
Tell me plainly: my voice and the reply text go to Fish, even when the brain is local.
What it does, in order
- Make an account at fish.audio, get a key and save it in
~/.config/fish-voice.env - Check the key works
- Pick a voice, or clone your own
- Text to speech
- Speech to text
- The voice loop: you talk, your model thinks, it talks back
Fish is a cloud service. Your voice and the reply text go to Fish, even when the brain is local. Clone only your own voice, or a voice you have written consent for.
Check the result
Listen for clear pronunciation, compare the transcript with the original sentence, and record the actual usage cost. The CNERD end-to-end voice walkthrough is pending; this page does not claim a completed live test.
Part 5 · Connect your own devices
Reach it from anywhere
Referral link: CNERD may receive a benefit if you sign up through this link.
Copy this one prompt
Paste it into Claude Code on your computer. Claude walks you through every step, from buying the VPS to talking to your assistant on your phone. Send it a screenshot if you get stuck.
Walk me through putting my AI assistant on a Hostinger VPS, from nothing to working on my phone. I am not technical.

Rules:
- One step at a time. Tell me exactly what to click or paste, then wait for me to say done. If I send a screenshot, read it and tell me what to do next.
- If I have already done a step, skip it.
- Do everything you can yourself. Stop only for what only I can do: paying, signing in, approving, making keys.
- Never ask me to paste a password or key into this chat. Never print one.
- No model runs on this VPS, because it has no GPU. The brain is an API.

First ask me two things: where my assistant lives (a GitHub link or a folder on this computer), and how far I have got.

Steps:
1. Review a VPS plan using https://www.hostinger.com?REFERRALCODE=1JXZMIKEAHUE. Confirm the resources, current price, renewal cost, region, and supported Ubuntu LTS version. Wait for me to complete any purchase. Help me save access details in my password manager without displaying them.
2. Tailscale on my computer and my phone. First explain in one plain line what it is: a private tunnel between my own devices. The VPS still runs 24/7 without it. I install it from https://tailscale.com/download and sign in with the same account on both.
3. Update the server first. In Hostinger I press Manage VPS, then Web console at the top right, and log in as root. I paste this. It installs all updates and restarts the server, so the black screen disconnects. I wait a minute, then open the Web console again:
apt update && DEBIAN_FRONTEND=noninteractive apt upgrade -y && reboot
4. Tailscale on the VPS. In the Web console, I paste this, then wait for it to finish:
curl -fsSL https://tailscale.com/install.sh | sh
Then I paste this, open the link it prints, and approve the VPS:
sudo tailscale up --ssh
5. Check. I open https://login.tailscale.com/admin/machines and should see 3 devices. Ask me for the VPS name.
6. Make Tailscale one-way. Explain in one plain line why: by default every device can reach every other one, so a broken server could reach my computer. Give me this policy to paste in https://login.tailscale.com/admin/acls (JSON editor, replace everything, Save). Then tell me to add tag:server to the VPS in Machines, and to turn off Allow incoming connections in Tailscale on my computer:
{"tagOwners":{"tag:server":["autogroup:admin"]},"grants":[{"src":["autogroup:member"],"dst":["tag:server"],"ip":["*"]},{"src":["autogroup:member"],"dst":["autogroup:self"],"ip":["*"]}],"ssh":[{"action":"check","src":["autogroup:member"],"dst":["tag:server"],"users":["root","autogroup:nonroot"]}]}
Now Tailscale asks me to approve each new login in my browser. That is on purpose.
7. From here you do the work. Connect with: ssh root@VPS-NAME. If Tailscale asks me to approve it in a browser, tell me. If it fails, tell me the exact error.
8. Tell me how to get back in through Hostinger's Web console, and how to reset the firewall in its Settings page, and wait for my OK. Then block all incoming traffic except Tailscale with ufw. Test that SSH still works. Turn off SSH password logins and root login from the internet, but first check how Hostinger's Web console logs in, and ask me if a change would break it.
9. Check that the server is fully up to date, and that automatic security updates are on. If it still needs a restart, tell me, restart it, and check that Tailscale and SSH come back. I can ignore the ESM message, because it needs an Ubuntu Pro account.
10. Make a normal user to run the app. Copy my assistant over with rsync from this computer, so the VPS needs no GitHub login. Leave out node_modules and env files. Read its README and install what it needs.
11. Ask me for new API keys, made only for this VPS, with spend limits. Tell me the exact file for them, with mode 600. I paste them in myself. Do not copy my computer's key file.
12. Run it as a service that listens only on the VPS itself and restarts by itself. Then run tailscale serve in the background on its port, so only my devices can reach it. Never use tailscale funnel. If the app refuses the tunnel's address, allow only that one address. If it has no login, tell me and ask before you add one.
13. Check that the VPS's public address has no open port. From the VPS, check that it cannot reach my computer or my phone. Check that key files are mode 600, the app does not run as root, and nothing else listens that I do not need. Give me the exact address to open on my phone, with Tailscale on.
14. I shut my computer and ask my assistant something from my phone.
15. List what now lives on the VPS. Tell me plainly what you could not test.
Not tested from start to finish yet. On your first run, keep Hostinger's Web console open. It gets you back in if the firewall locks you out.
Or follow it yourself, step by step
Use the CNERD referral link above. Compare the plan requirements for your project.
Pick a suitable location and review the plan and renewal price. Use the CNERD referral link above; no separate coupon code is supplied.
Pick the newest LTS version. No panel, no app.
Press Generate and save it in your password manager. Skip the SSH key.
Monarx is a free malware scanner. Then press Finish setup.
This is what you see when your VPS is ready. Skip the free domain.
Then press Web console, at the top right. Log in as root, with the password you saved.
Why: your computer and your server need a private line to talk to each other. Tailscale is that line.
- Go to tailscale.com/download and press the button for your computer.
- Open the file it downloads and install it.
- A popup asks to add VPN configurations. Press Allow.
- Sign in. Remember which account you used. You use the same one on every device.
Done when: a small Tailscale icon sits at the top of your screen.
- Get Tailscale from the App Store or Google Play.
- Sign in with the same account.
- Turn it on, and press Allow if it asks.
Why: a new server comes with old software. This installs all the latest security fixes.
- Go back to the black screen from step 6.
- Press Copy below. Click the black screen. Paste with Cmd+V, then press Return.
apt update && DEBIAN_FRONTEND=noninteractive apt upgrade -y && reboot
Done when: the black screen disconnects, because the server is restarting. Wait a minute, then press Web console again and log in.
Why: this is the only part Claude cannot do, because it has no way into your server yet. You paste 3 lines in total, and then it can.
- Press Copy below. Click the black screen. Paste with Cmd+V, then press Return.
curl -fsSL https://tailscale.com/install.sh | sh
Done when: it says "Installation complete!" and you see the root@ line again. It takes about a minute.
Why: this tells Tailscale the server is yours, so it joins your private line.
- Paste this into the black screen and press Return.
sudo tailscale up --ssh
- A web link appears on the black screen. Copy it and open it in your browser.
- Sign in with the same account, then press Connect.
Done when: the black screen says Success.
Done when: you see 3 rows: your computer, your phone and your server.
Why: by default, every Tailscale device can reach every other one, both ways. If someone ever broke into your server, they could then reach your computer. This rule stops that. Your devices can reach the server. The server can reach none of them.
- Open Access controls and pick the JSON editor.
- Delete everything there. Paste the code below. Press Save.
- Open Machines. On your server's row, press the three dots, then Edit ACL tags. Add tag:server and save.
- On your computer, open the Tailscale menu and turn off Allow incoming connections. Skip this only if you reach your computer from your phone.
{
  "tagOwners": { "tag:server": ["autogroup:admin"] },
  "grants": [
    { "src": ["autogroup:member"], "dst": ["tag:server"], "ip": ["*"] },
    { "src": ["autogroup:member"], "dst": ["autogroup:self"], "ip": ["*"] }
  ],
  "ssh": [
    { "action": "check", "src": ["autogroup:member"], "dst": ["tag:server"], "users": ["root", "autogroup:nonroot"] }
  ]
}
Tailscale will now ask you to approve each new login to the server in your browser. That is on purpose. Claude will tell you when.
Done when: your server's row shows tag:server. In step 15, Claude checks that the server cannot reach your computer.
You are finished with the black screen. From here, Claude types everything.
- Open Claude Code on your computer.
- Paste the prompt from the top of this page.
- Tell it: "Tailscale is done on all 3 devices."
- Do what it asks. It stops only for things you must do yourself, like making new API keys with a spend limit.
Then paste this, to bring the server fully up to date. Updates are the security fixes and new software that came out after your server's copy of Ubuntu was made.
Connect to my VPS over Tailscale and bring it fully up to date. Show me what needs updating, then install it all. Check that automatic security updates are on. If it needs a restart, tell me, restart it, and check that Tailscale and SSH come back. Then tell me what you updated, in plain words.
Done when: it gives you a web address for your phone.
Why: this checks every lock, one by one, and closes anything left open.
Connect to my VPS over Tailscale and lock it down as tight as you can, without locking me out. Before each change, tell me what it does in one plain line. Then check each item and tell me pass or fail:
1. Tailscale is one-way. From the VPS, try to reach my computer and my phone. It must fail.
2. The firewall blocks all incoming traffic except Tailscale. From my computer, check that the VPS's public address has no open port.
3. SSH: no password logins and no root login from the internet. First find out how Hostinger's Web console logs in. If a change would break the Web console, stop and ask me.
4. My assistant runs as a normal user, not root, and listens only on the VPS itself. Only tailscale serve reaches it. No tailscale funnel.
5. Key files have mode 600. No key is in git, in logs or in the chat.
6. Automatic security updates are on, and Monarx is running.
7. Nothing else is listening that I do not need. List what is listening and ask me before you stop anything.
Then give me a short pass and fail list, in plain words.
Done when: every line says pass.
- Shut your computer.
- Turn Tailscale on, on your phone.
- Open the web address and ask your assistant something.
Done when: it answers with your computer shut.
What can it run?
Your own OS, Claude Code and your agents all live on this server. For the thinking, plug in any API you like: Claude, DeepSeek or something else. The model itself does not run on this server, because it has no GPU. It answers over the internet.
How it stays safe
- Nothing faces the internet. Only your own devices can reach it.
- The firewall allows only Tailscale. Never use Tailscale Funnel.
- Fully up to date. You update first, and Claude keeps automatic security updates on.
- New keys, with spend limits. Never copy your computer's key file.
- One-way only. Your devices reach the server. The server reaches none of them.
- You approve each login. Tailscale asks you in your browser before anyone gets into the server.
- 2-step login everywhere. Turn it on for Tailscale, Hostinger and every AI account you use.
- Keep your server address private. Never show its IP or name on screen or in a screenshot.
- Your computer shares nothing. Do not turn on subnet router or exit node in Tailscale.
- Locked out? Hostinger's Web console still gets you in. You can also reset the firewall in the VPS Settings page.
What is Tailscale?
A private tunnel between your own devices. Your VPS stays hidden from the internet, and only your phone and computer can reach it.
- Your VPS still runs 24/7. Tailscale is only the way in, like the key to a locked door. Jobs keep running when your phone and computer are off.
- To talk to it, turn Tailscale on, on your phone.
- Keep the brain on an API. If the brain is your home computer, it stops when that computer is off.
Why you want this
Level 1 sends your words to their server. Level 2 keeps them private, but your assistant is stuck at one desk.
What a server gives you
- Reach your assistant from your phone.
- Jobs finish while your computer is shut.
Two ways in
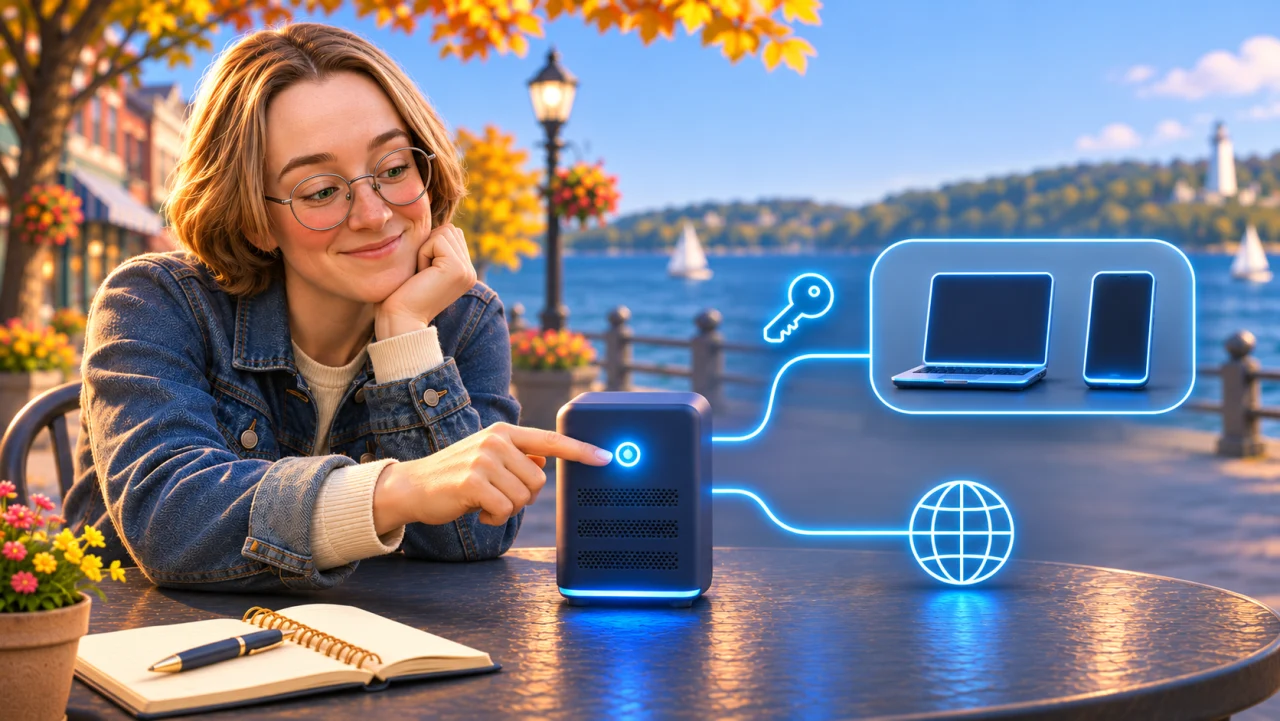
- Private tunnel: an app on each device, like Tailscale. Nothing faces the internet. Pick this if it holds your memory and keys.
- Public domain: HTTPS and a login. No app needed, but it faces the internet.
This part is not local. The server holds a copy of your data and keys. A small server has no GPU, so the brain is an API or your home computer. These steps are a plan: neither way in has been tested on a real server for this pack.
Want a plan first?
Help me reach my AI assistant from anywhere. Write the plan first, then wait for my OK.

The problem: it only works at one desk, and it stops when my computer sleeps.
1. Tell me what will run where. A small server has no GPU. So the brain is an API, or my home computer over a private tunnel.
2. List the jobs that should keep running while my computer is shut.
3. Voice needs HTTPS, because browser microphones require it.
4. List every key and file that will live on the server. Tell me plainly: this part is not local.
5. Give me the monthly bill.
Build something useful. Then build on it.
Start with one fictional job, one useful result, and one improvement you can measure.
Space reserved for our community channel.
Technical references · verify before use
- abliteration.ai/pricing
- arxiv.org/abs/2406.11717
- docs.abliteration.ai/integrations/claude-code.md
- docs.abliteration.ai/models.md
- docs.abliteration.ai/what-is-abliteration.md
- docs.fish.audio/developer-guide/models-pricing/pricing-and-rate-limits.md
- docs.ollama.com/context-length
- docs.ollama.com/integrations/claude-code
- epoch.ai/benchmarks/eci
- epoch.ai/data-insights/open-closed-eci-gap
- github.com/morluto/rea
- ollama.com/download
- ollama.com/eriktonon/deepseek-v4.1-flash-1017/tags
- ollama.com/huihui_ai/Qwen3.8-abliterated/tags
- ollama.com/huihui_ai/deepseek-r1-abliterated/tags
- ollama.com/huihui_ai/devstral-2-abliterated/tags
- ollama.com/huihui_ai/gemma-4-abliterated/tags
- ollama.com/huihui_ai/glm-4.7-flash-abliterated/tags
- ollama.com/huihui_ai/qwen3-next-abliterated/tags
- ollama.com/huihui_ai/qwen3.5-abliterated/tags
- ollama.com/library/deepseek-r1/tags
- ollama.com/library/gemma4/tags
- ollama.com/library/glm-4.7-flash/tags
- ollama.com/library/gpt-oss/tags
- ollama.com/library/qwen3.5/tags
- ollama.com/library/qwen3.8/tags
- ollama.com/orcarouter/Qwen3.8-27B-Uncensored/tags
- platform.claude.com/docs/en/about-claude/pricing
- Hostinger · CNERD referral
CNERD AI · Local AI Workbench · v0.3.0
CNERD Family artwork. Episode recording and technical validation are in progress.